Automate chromatogram import from instruments
While it’s possible to just drag’n’drop raw files into Peaksel, most organizations will benefit from setting up automatic import. This way your administrator can set up all the locations and the scientists will never have to deal with raw files and folders - everything is going to be manageable using Peaksel interface. The process looks like this:
-
Specify locations where instruments write raw data
-
Peaksel looks for the new raw files every several minutes (this delay is configurable)
-
Once discovered, the data is automatically loaded and processed
-
When scientists open Peaksel, they see the new data and don’t have to deal with files and folders
Configuring vendor folders
Peaksel is able to import the data located:
-
In a Windows shared folder (aka SMB)
-
At FTP/S server. Could be yours or an open database like MassIVE.
-
On the local disk where Peaksel is running
For this open an organization that you created, then Org Menu (arrow next to the org name) → Settings → Import and press Add location:
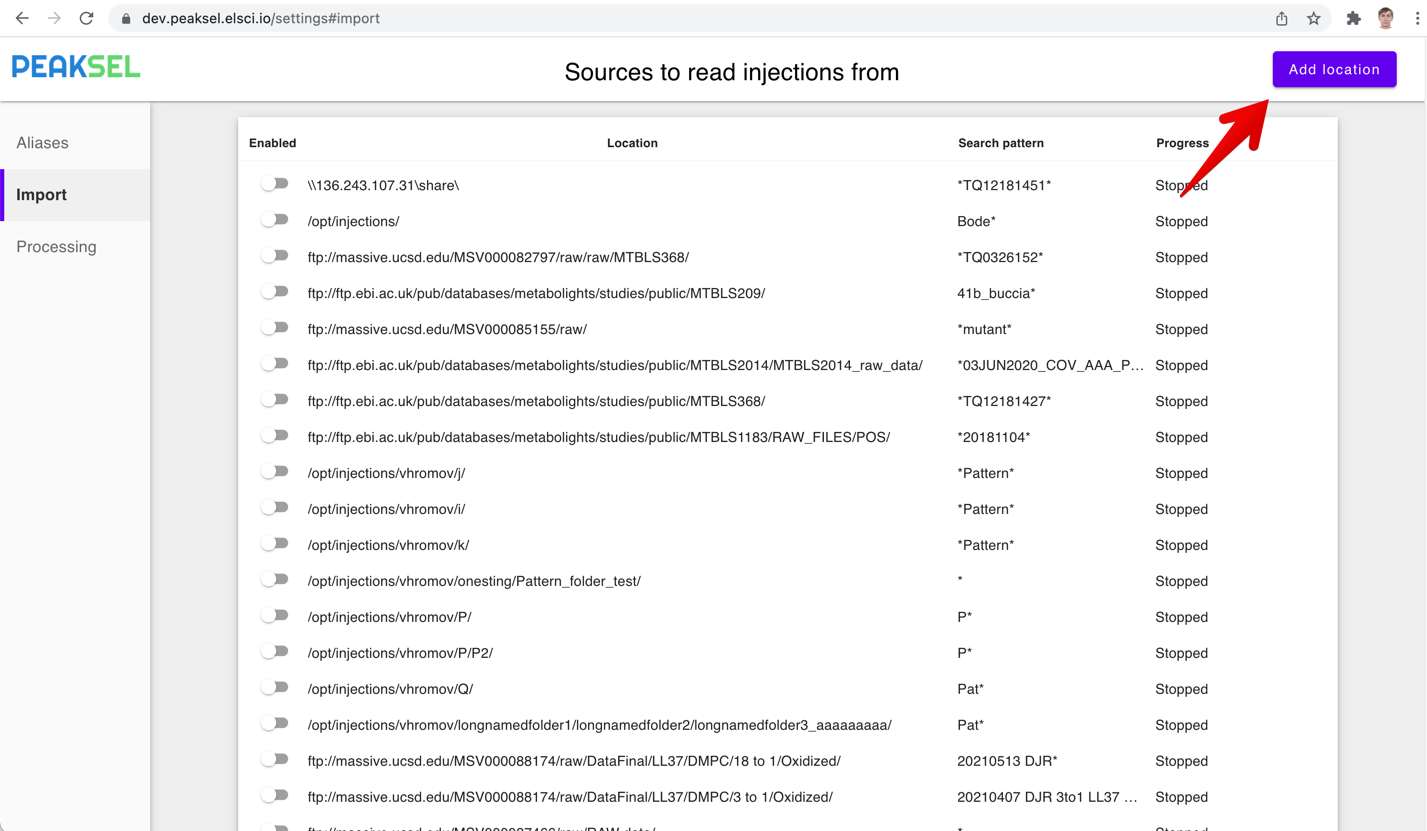
After that you’ll need to enter the actual location and possibly the credentials to access the raw vendor files:
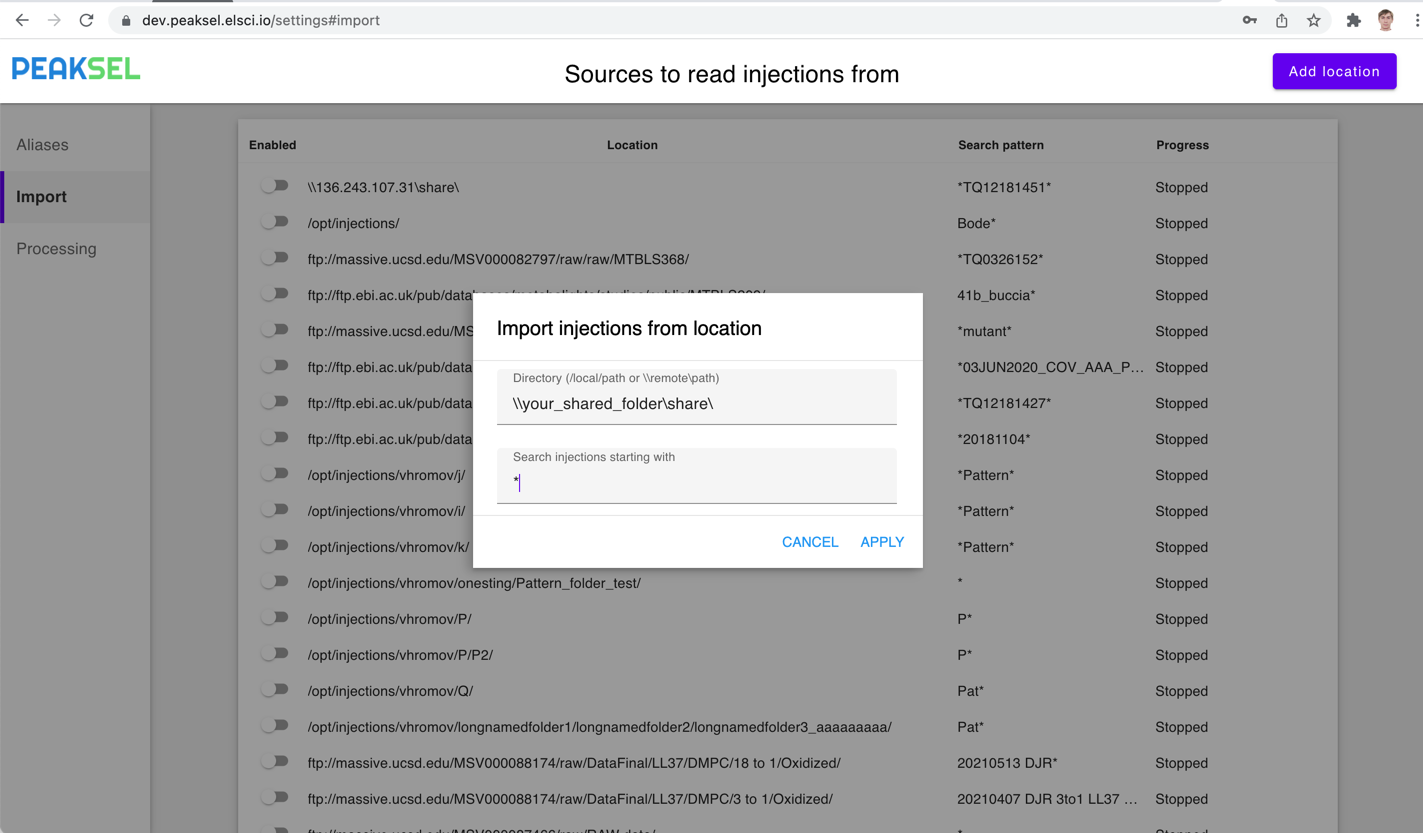
Then just turn on the importing and it will discover the files. You can add as many of these locations as needed. And you can turn on and off them at any point in time.
File discovery and import timing
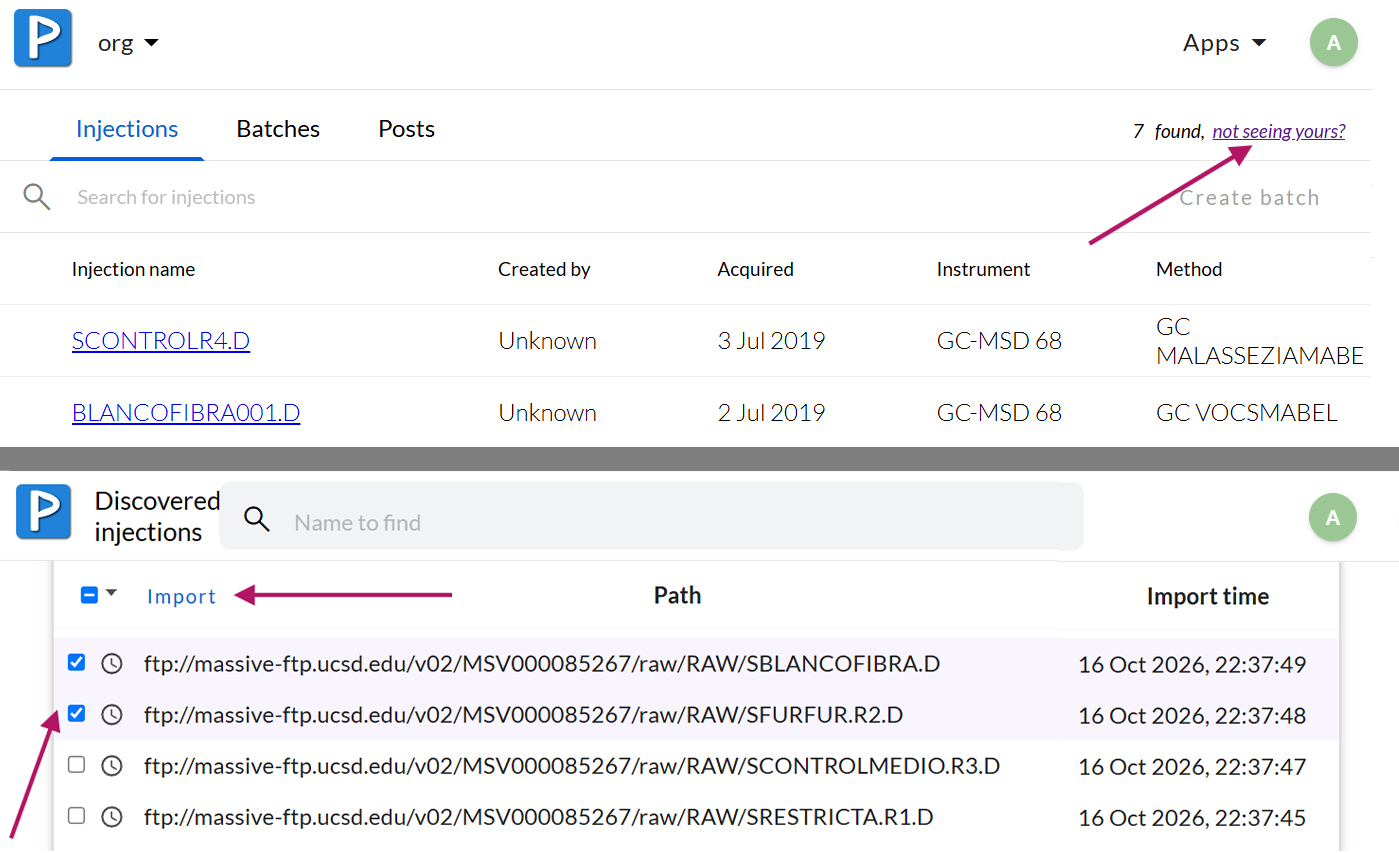
Before initiating the import, Peaksel must verify that the file has been completely written to disk. If a raw file has just finished recording, there will be a slight delay between discovery and import to prevent reading incomplete data. In such cases, if your data files have already been discovered and you don’t want to wait, you can view them under Discovered Injections and trigger a force import manually.
|
Re-importing data
Once a file has been discovered and successfully imported, the crawler will not reload it. If for some reason you need to do a re-import, there are a few ways to do this:
|